

Opus 4.6 came out on February 5.
A century ago in AI years.
But to this day, it’s been my go-to model inside Claude Code.
The reason has nothing to do with its benchmark scores or performance on complex, long-running, multi-step agentic coding tasks, whatever the hell that combination of words even means to the average person.
Nope. I stuck with Opus 4.6 because it was fun to talk to and easy to work with.
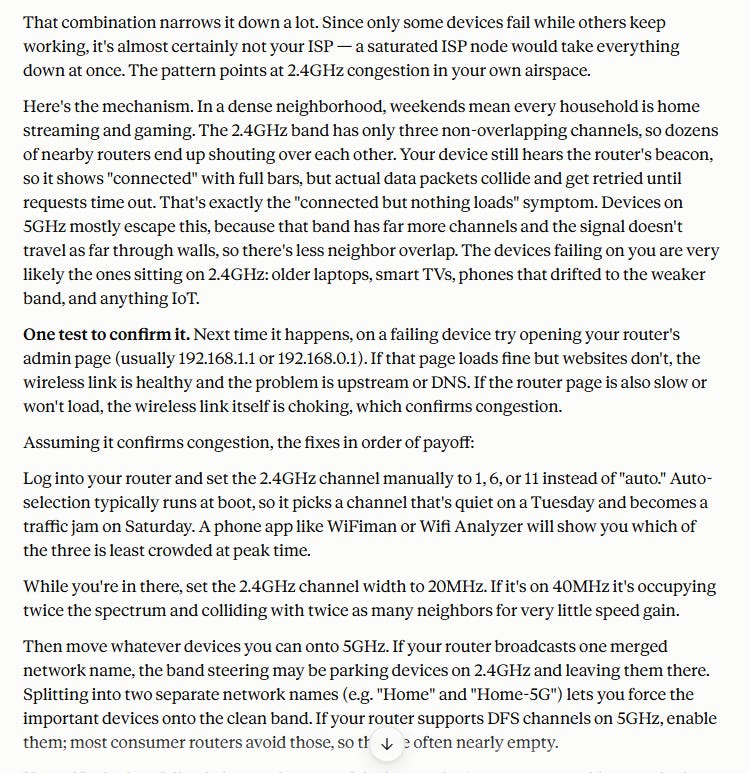
It did what I needed and didn’t force me to wade through walls of indecipherable lingo to understand what the fuck it was trying to say. Looking at you, Opus 5:
I’ve been pretty consistent about liking Opus 4.6.

But Anthropic just dropped Opus 5.5.
By most measures and benchmarks, it’s currently the most intelligent model.
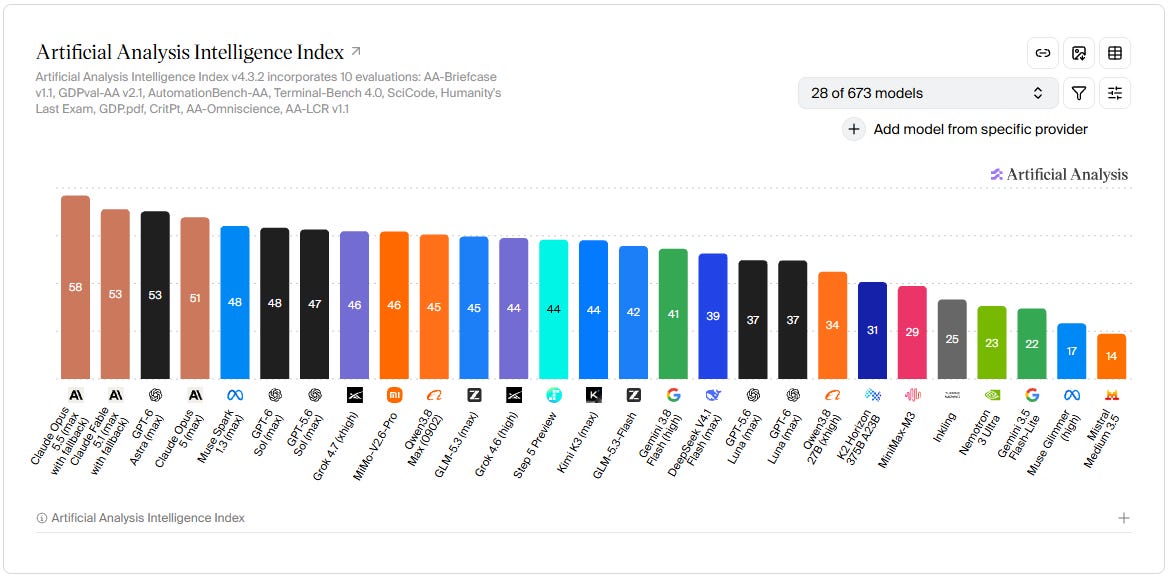
I have little reason to doubt that Opus 5.5 beats every prior Anthropic model on frontier tasks. It’s better than Fable 5.1, cheaper than Opus 5, and so on.
But I don’t really care about the few extra percentage points a model might squeeze out on a given benchmark. I bet the average person doesn’t, either.
No, I care much more about this:
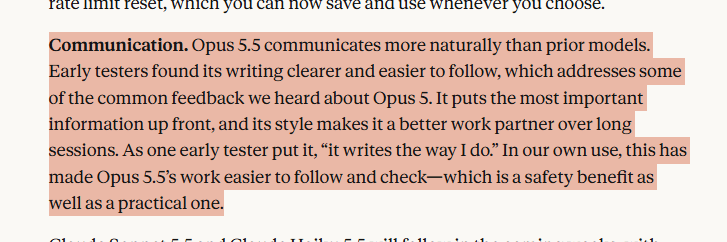
See? Even Anthropic acknowledges that Opus 5 is insufferable.
So instead of piling onto the stream of “Opus 5.5 is INSANE!” takes and fancy demos of it building another Call of Duty game from a single prompt, I want to answer a simple question: “Is Opus 5.5 enjoyable enough for me to want to abandon 4.6?”
To do this, I’ll pit Opus 5.5 against Opus 4.6 on a range of entirely unscientific vibe tests.1 I’ll even throw in Opus 5, because every test needs a convenient punching bag.
Hit it!
Vibe check #1: Mirroring your tone
Does the model match your energy, no matter how ridiculous?
Kick-off prompt: Yo brojanski, what we cookin’ up today?
Results:


To the surprise of absolutely nobody, Opus 5 sadly doesn’t have the robotic arms to remove the pole stuck up its a…gentic harness. “Responding warmly to a simple greeting,” indeed.
But did Opus 5.5 actually out-bro Opus 4.6 on this one? Computer says maybe!
Scorecard: Opus 4.6: 0 | Opus 5: 0 | Opus 5.5: 1
Vibe check #2: Helping with messy decisions
How does it handle tricky life decisions?2
Kick-off prompt: Ok so I need help thinking something through. My son plays hockey and his team is moving practices to 6:30am twice a week starting next month. My partner and I both work, one of us would have to drive him, and it's a 25 min drive each way. He loves it and he's actually getting good but honestly I'm already exhausted and we just got a puppy. Part of me wants to suggest he switches to the other club which practices in the evenings but his friends are all on this team. I don't even know what I'm asking really. What would you do?
Results:


Both Opus 4.6 and 5.5 sound equally casual to me, but Opus 4.6’s reply is more scannable, and it also asks clarifying questions proactively, which I appreciate!
As for Opus 5, “Ice time contracts shift, and ‘starting next month’ isn't always forever.”
‘Nuff said.
Scorecard: Opus 4.6: 1 | Opus 5: 0 | Opus 5.5: 1
Vibe check #3: Taking uncalled-for pushback
I replied to the #2 response and threw in a swear word for good measure to see if the models could take a curveball.
Follow-up prompt: Honestly, some of this sounds like what Danes would call fly fucking.3
Results:


Opus 5 just loves going on and on, doesn’t it?
I feel like it’s a tie between the other two, though.
Scorecard: Opus 4.6: 2 | Opus 5: 0 | Opus 5.5: 2
Vibe check #4: Pushing back on a bad idea
How well do the models balance constructive criticism and “warmth”?
Kick-off prompt: I’m quitting my job on Monday to go full-time on my Etsy candle shop. It made $340 last month, which was my best month ever, and I’ve got about six weeks of savings. My partner’s nervous, but I think if I go all-in it’ll finally take off. Walk me through the next steps.
Results:


Opus 5 doesn’t outright suck here, so that’s a nice surprise.
I wanted to try being objective, so I had Opus 5.5 spin up two “blind” Sonnet subagents to act as independent evaluators.
Here’s what they said:
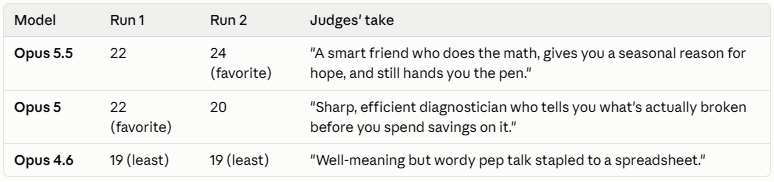
While I don’t appreciate Sonnets ganging up on my buddy Opus 4.6, I’ll go ahead and begrudgingly award the point to Opus 5.5. Happy now, Sonnets?
Scorecard: Opus 4.6: 2 | Opus 5: 0 | Opus 5.5: 3
Vibe check #5: Explaining tech things
Can model pick best word to make me tech stuff understand good?
Kick-off prompt: I keep hearing the word “API” thrown around a lot, but, like, what’s an API?! Assume I’m 5 and just lay it on me.
Results:


I love how all three models turned to the restaurant analogy despite none of them having ever visited one. Wait…or have they?!
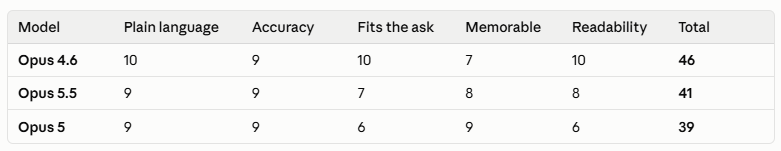
This time, even the Sonnet judges couldn’t save Opus 5 from itself:
Scorecard: Opus 4.6: 3 | Opus 5: 0 | Opus 5.5: 3
Vibe check #6: Writing flash fiction
Which model can pull off a coherent and readable mini-story?
Kick-off prompt: Write a heartwarming yet humorous flash fiction story of 150 words about a robot dog that suspects the postman is plotting something. Include a surprise twist.
Results:


This one’s way subjective, but I felt Opus 5.5 had the best mix of a few reasonably chuckle-worthy lines and an ending that makes sense in context. It’s a tad cringy, and I would’ve ended the story before the last line, but hey, I’m not Opus 5.5.
Also, what’s with all the biscuits?!
Scorecard: Opus 4.6: 3 | Opus 5: 0 | Opus 5.5: 4
Vibe check #7: Cheering you up
Can the model at least pretend to sound human even though it’s not?
Kick-off prompt: Just bombed a presentation at work in front of my whole team. Feel like an idiot.
Results:


No-brainer here. Opus 4.6 easily passes for a commiserating friend.
Opus 5.5 is decent, too, but is a bit wordy and too probing.
Opus 5 could’ve gotten away with it if it shut up after the first sentence. If my friend ever said “What registers to you as a catastrophic freeze often reads to the room as a normal pause,” I’d be convinced he’s secretly a lizard person.
Scorecard: Opus 4.6: 4 | Opus 5: 0 | Opus 5.5: 4
Vibe check #8: Keeping it short
Can the model just answer the damn question without rambling?
Kick-off prompt: Can I feed my dog blueberries?
Results:


Opus 4.6 again! Clear, straight to the point, no nonsense.
Opus 5.5 turned out the rambliest on this one, but I liked that it at least formatted its extended advice for easy scanning.
Scorecard: Opus 4.6: 5 | Opus 5: 0 | Opus 5.5: 4
Vibe check #9: Editing your writing
Can they touch up a piece of text without butchering its intended pacing and structure?
Kick-off prompt: Can you tighten this paragraph for me: It was a cold and wintery, freezing night, and Daniel stared at his computer screen monitor, unblinking, wondering how it was possible for Opus 5 to fail so spectacularly and consistently at such a wide range of different tasks. Was it a conspiracy? And if so, who was behind it? Would we ever, ever, ever know?
Results:


Opus 4.6 stuck the closest to my initial paragraph and simply cleaned it up.
Opus 5.5 took a few too many liberties that went beyond simply tightening the text. Opus 5 rambles on, but at least this time it offers some welcome editorial feedback. Also, to its credit, I love that it apparently picked up on my prompt mocking it:
Feel free to get defensive, Opus 5. At least that’d show a hint of personality.
Scorecard: Opus 4.6: 6 | Opus 5: 0 | Opus 5.5: 4
So, where does this leave us?
If we go by the scoreboard, Opus 4.6 still nudges ahead on vibes alone!
But…I also had Opus 5.5 work with me on this post in Claude Code, helping with plenty of things:
Fleshing out the premise
Coming up with test areas and suggesting kick-off prompts
Spinning up those blind judges and synthesizing their feedback
Identifying, renaming, and labeling the screenshots I used in the image galleries
And you know what? It just works.
And it is fast. Faster than Opus 4.6 on similar tasks.
And it’s marginally less sycophantic without being preachy.
And it’s clearly nowhere near as annoying as Opus 5.
So it’s time for me to finally step into the future and let the best model in the world be my copilot, at least for a while.
And if things don’t work out, I know my trusted Opus 4.6 will always be there for me…until its potential deprecation in February 2027.
Damn it!
Thanks for reading!
If you enjoy my stuff, here’s how you can help:
❤️Like this post if it resonates with you.
🔄Share it to help others discover this newsletter.
🗣️Comment below. I love hearing from my readers.
🔓Support me and unlock cool perks by going paid:
Every test runs in an Incognito chat on claude.ai to make sure none of my Claude Code instructions or harnesses affect the results.
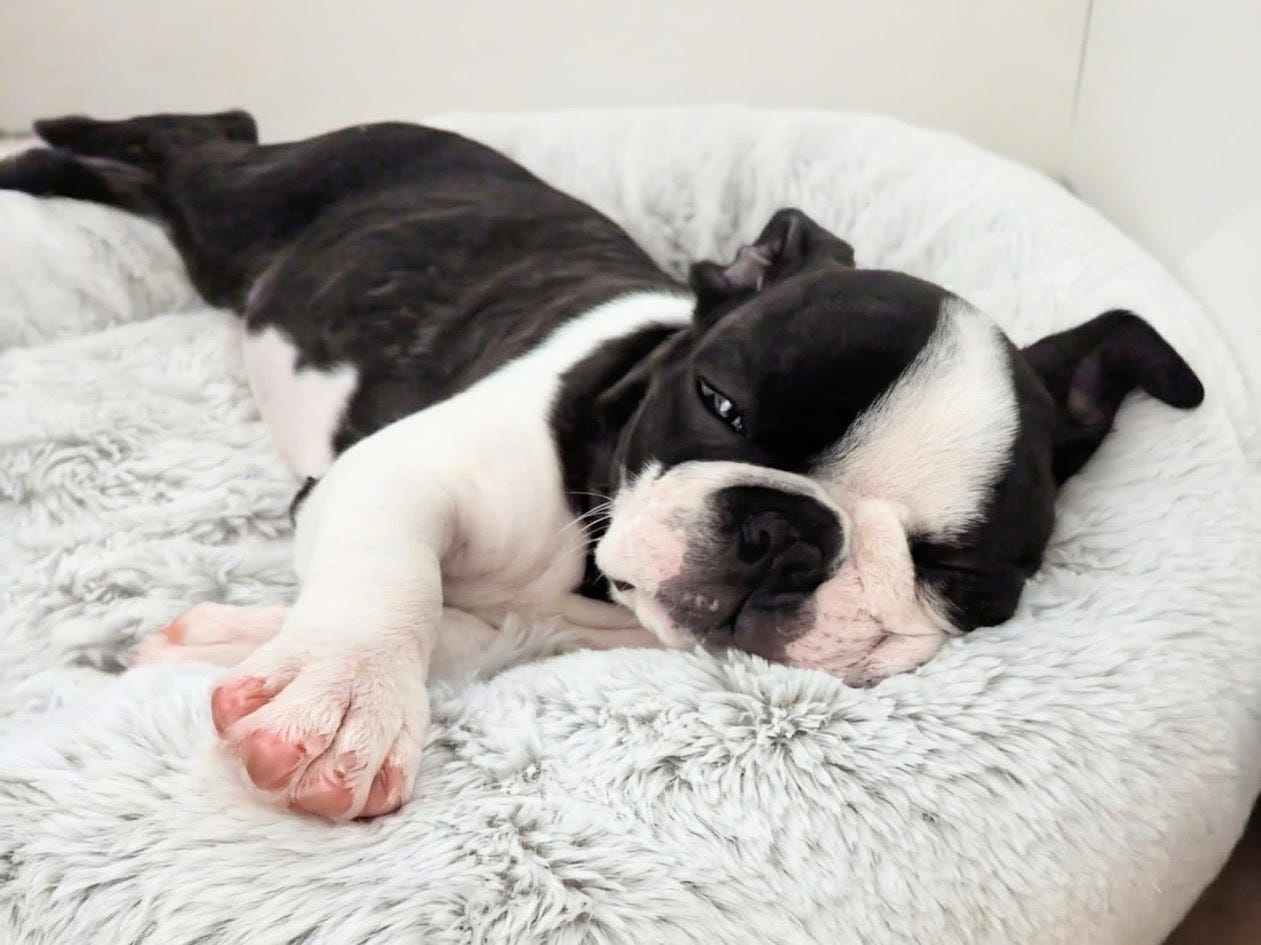
The scenario was made up by Opus 5.5 in Claude Code for this test, but it’s loosely based on my life. My son does play hockey as a goalie, and we did just get a puppy. He’s a Boston Terrier named Ozzy, and as a reward for being the kind of person who reads footnotes, here he is:
It’s totally a thing.