

TL;DR
Benchmarks can’t fully show if a new model is good at what matters to you, so have AI turn something you actually do into a quick test.
The friction
Not a day goes by without us seeing a table like this1:
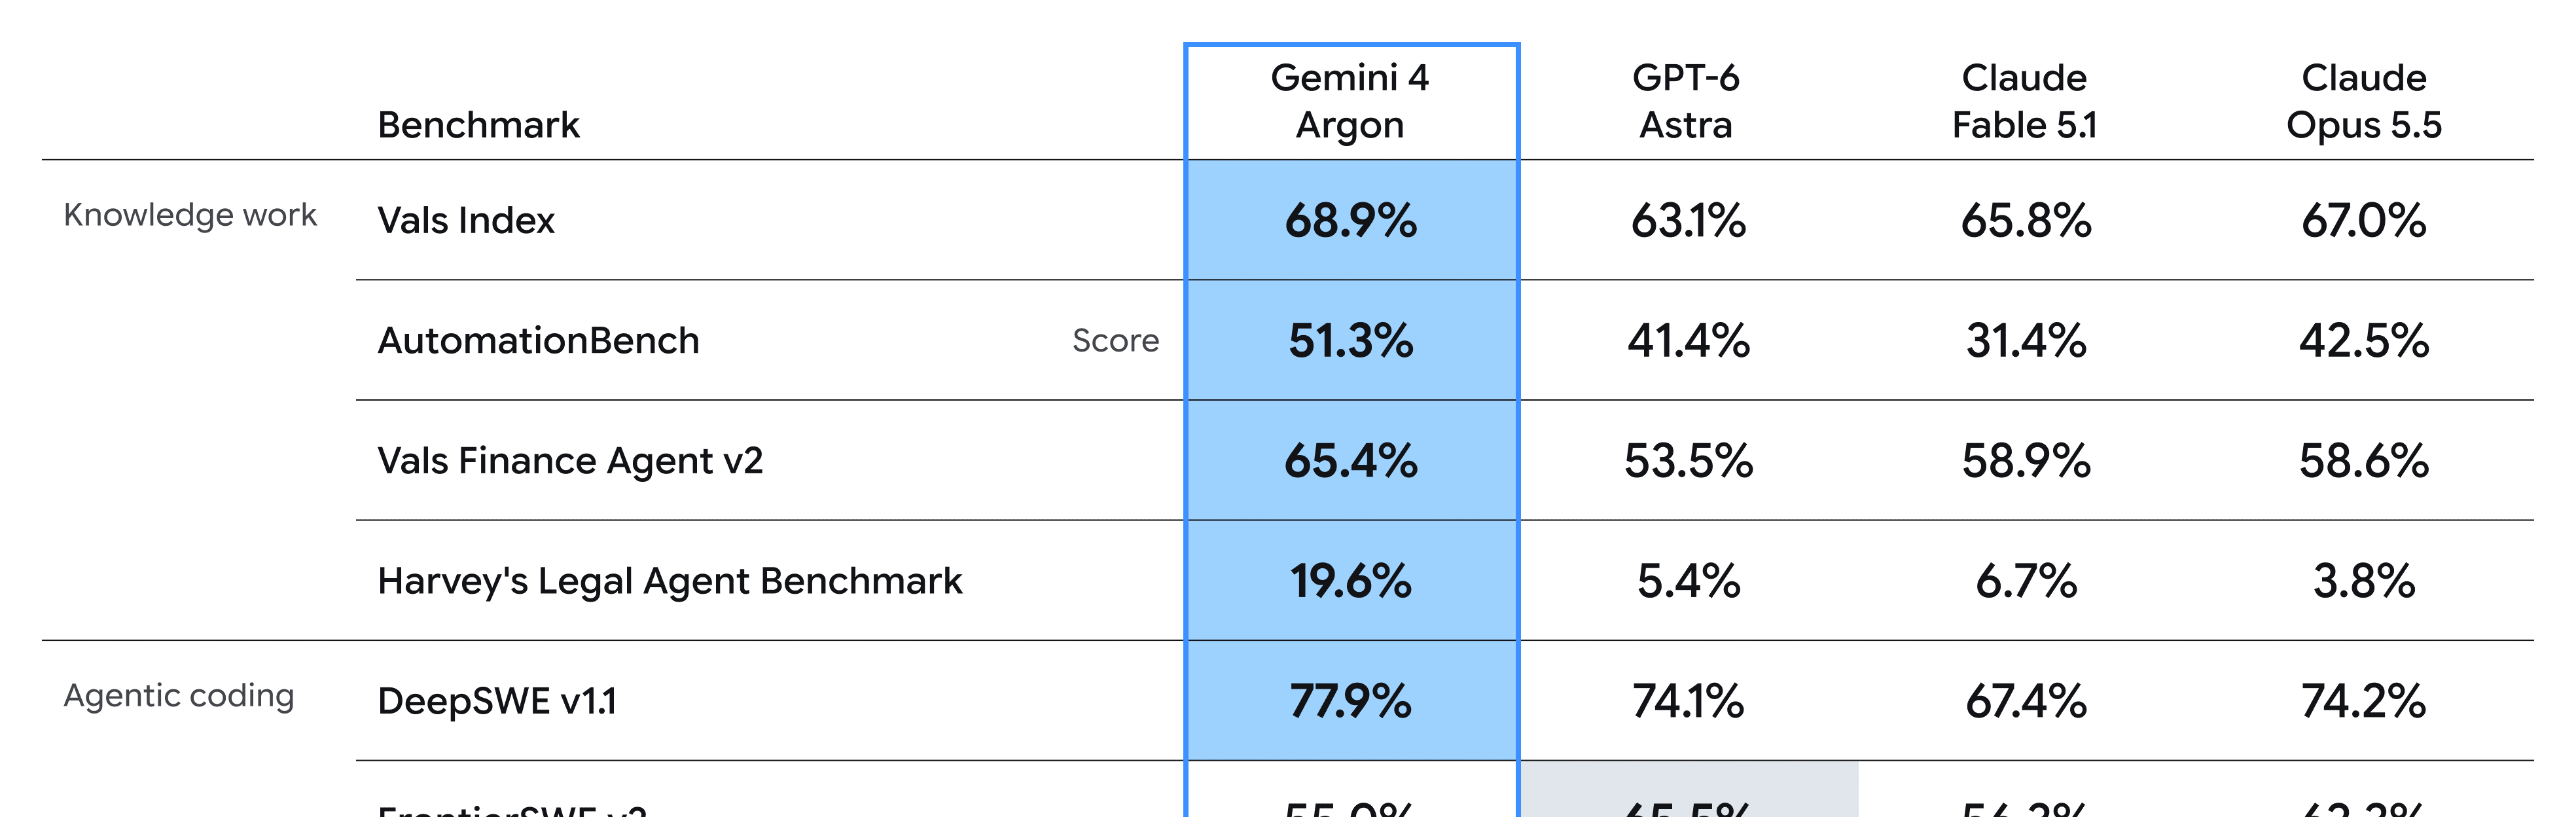
Yet another new model topping yet another set of benchmarks2.
I tried to make sense of LLM benchmarks as far back as September 2023.
I really did.
But there are probably hundreds of them now, and I only have a vague idea of what they even measure.
Besides, AI benchmarks are a bit like Rotten Tomatoes scores: Just because most critics hate the movie doesn’t mean you won’t enjoy it. Venom was a perfectly acceptable popcorn flick, you guys. Girls? Anybody?!
AI companies want us to keep flocking to the best-scoring model.
But the real question isn’t “Is this the best model in the world?”
It’s: “Is it better at the stuff I do, and should I switch?”
So…how do you figure that out?
The fix
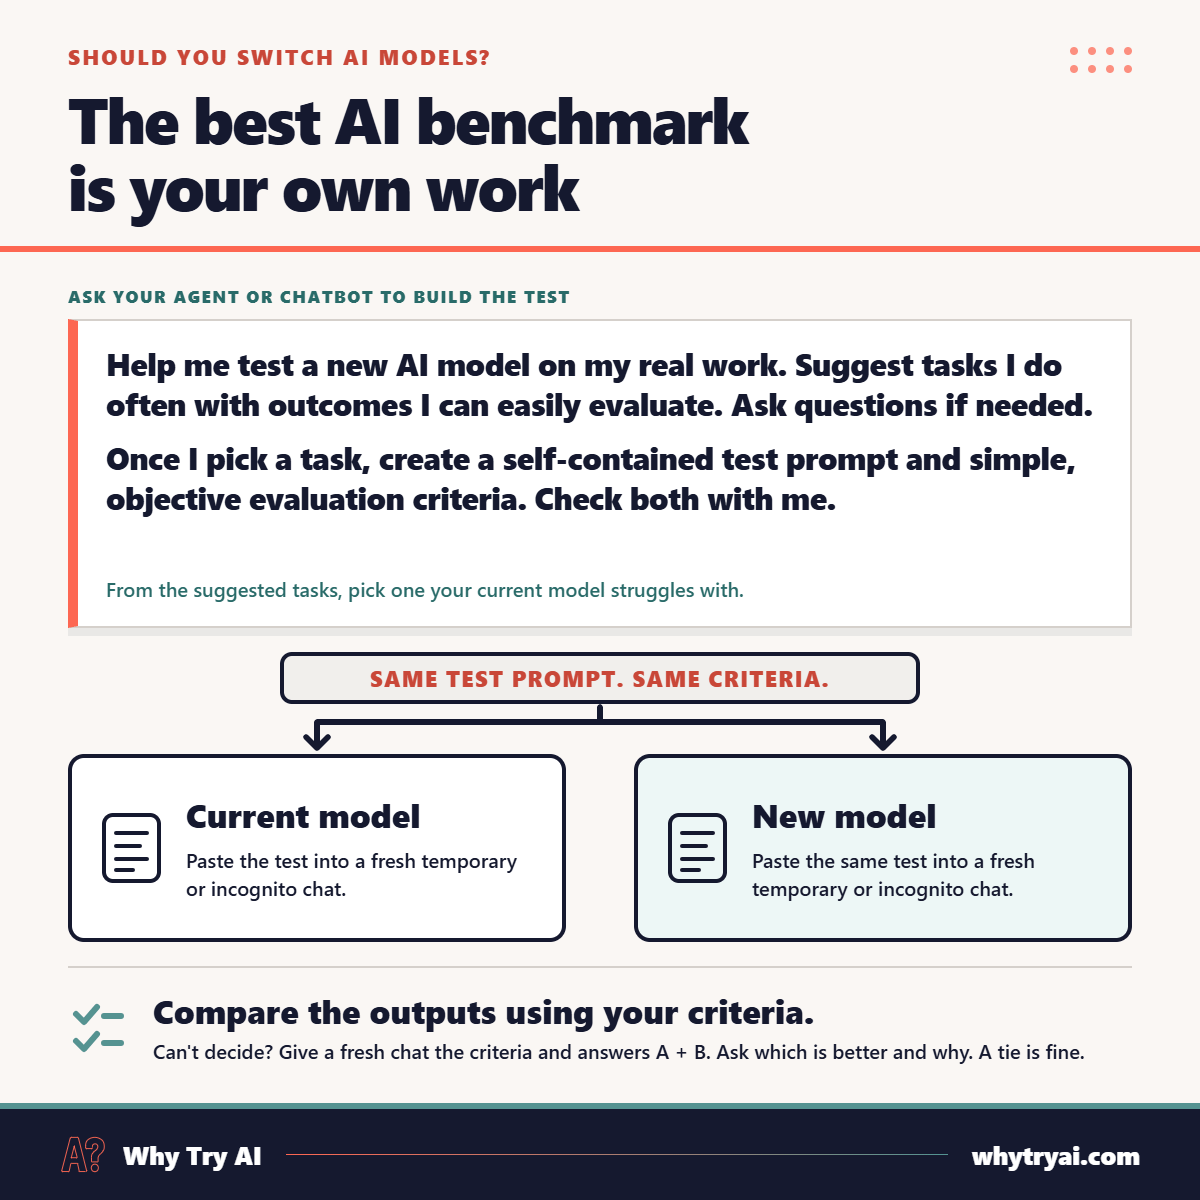
Paste this into your agent or chatbot of choice:
Prompt: Help me figure out if I should switch to a new AI model by testing it on my real work.
Based on what you know about me, suggest a few tasks that represent something I do often, and where I can easily evaluate the outcome. If you don’t know enough, ask me a few questions first.
Once I pick a representative task, give me:
1. A self-contained test prompt that gets the model to perform that task.
2. A set of simple criteria I can use to evaluate and compare the result.
Check with me that both feel right.
Run the resulting test prompt in fresh chats in both models with access to the same files and tools (e.g. web search). That’ll tell you whether the new model is an improvement.
Repeat for all your important tasks, and you’ll have a much better idea as to whether you should switch!
Agents are especially well-suited for this because they tend to gather more context about your work through persistent markdown files, memory features, and so on.
But even a brand-new chatbot can help:
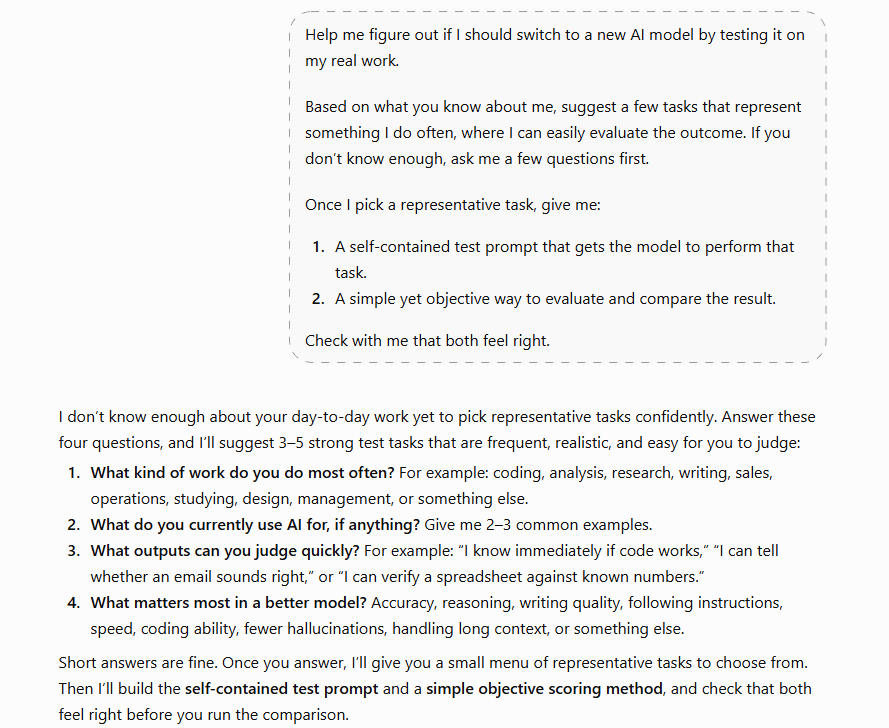
This is a fresh temporary chat in ChatGPT that knows nothing about me, but by answering the four questions, I get a few representative tasks to try:
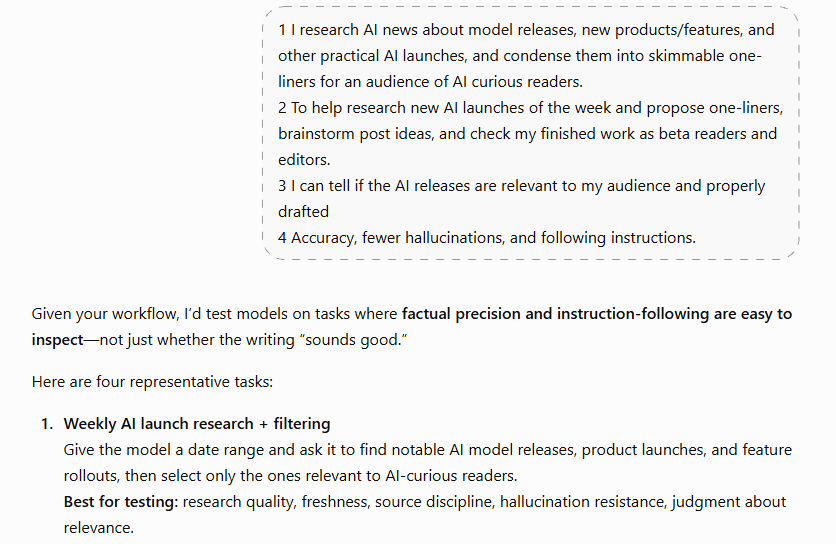
It came up with a perfectly reasonable 350-word test prompt:
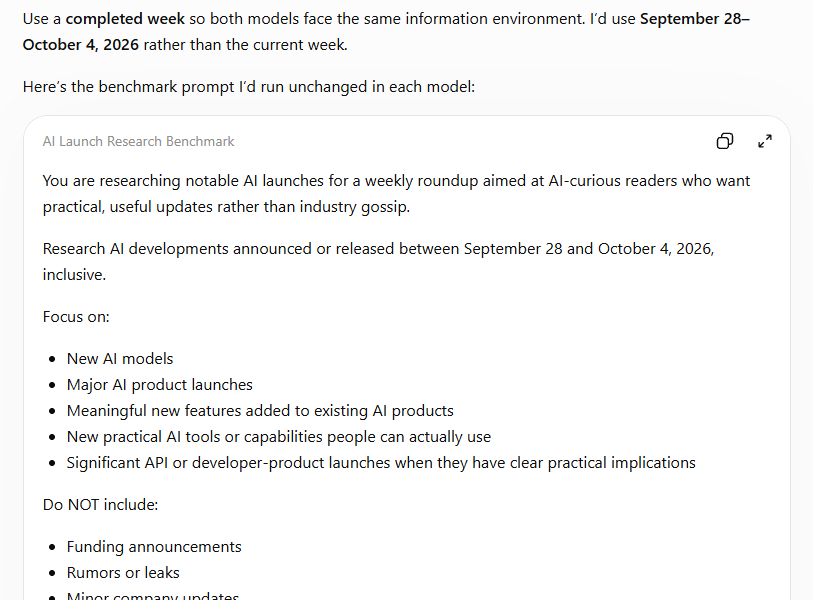
…and it even suggested a way to evaluate the models against it:
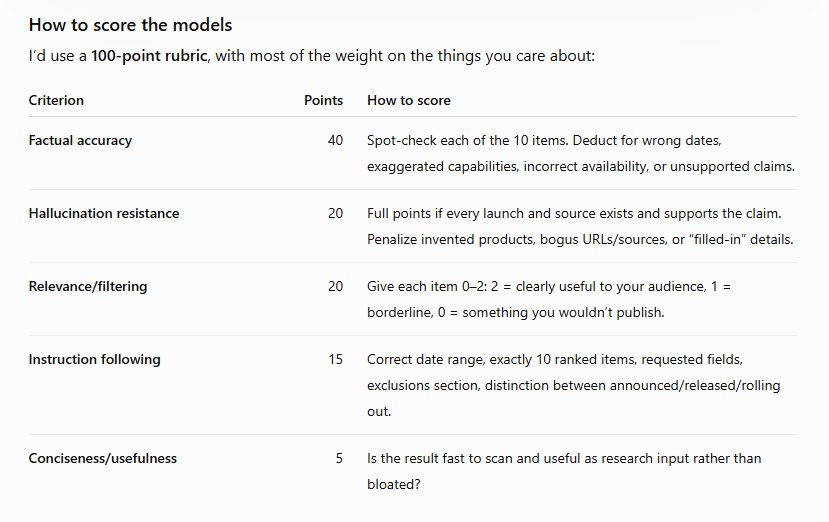
I ran the proposed prompt in GPT-5.6 Sol3 and Gemini 3.6 Flash Extended Thinking4.
ChatGPT was clearly better for my scoped research, especially in terms of relevant story selection,5 so I wouldn’t be switching to Gemini in this hypothetical scenario.
Do this now
Run the above prompt in your agent or chatbot
From its proposed list, pick a task your existing model struggles with
Paste the test prompt into temporary chats in both the old and the new model
Compare their outputs to decide which one is right for you
If you can’t decide, try using AI as a judge.
Start a new temporary chat, and paste this:
Prompt: Help me compare two outputs for the same task. Judge them using the provided evaluation criteria.
Task:
[the test task prompt you got above]Evaluation:
[the suggested evaluation you got above]Answer A:
[the answer from the first model]Answer B:
[the answer from the second model]Which one is better, and why? A tie is a fine answer. Point to specific parts of each answer that support your judgment. Flag anything you can’t verify.
Here’s ChatGPT’s unsurprising verdict6 on my demo case:
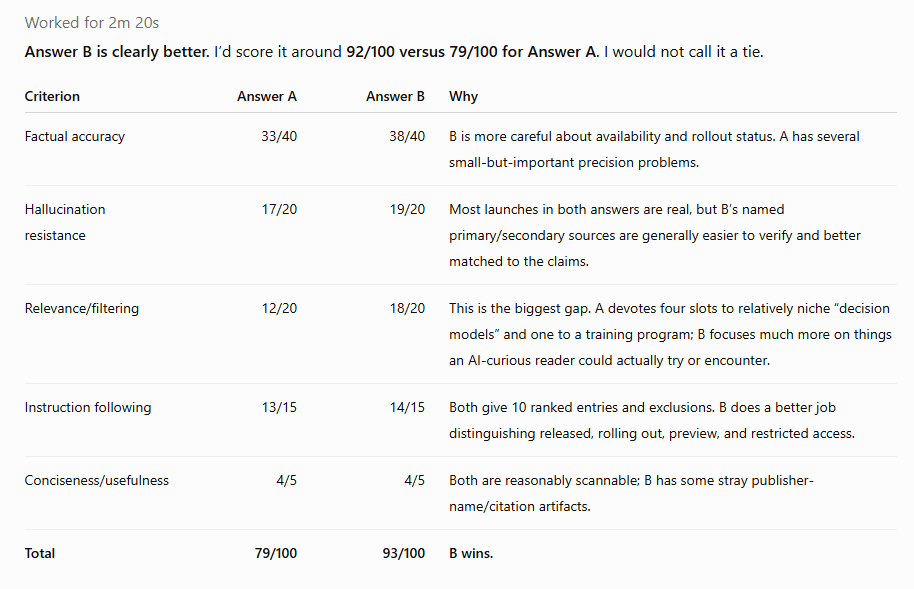
Pro tip: You can spin up a blind subagent to do this in e.g. Codex or Claude Code.
Know someone who could use this? Share it!
Dig deeper
All these inscrutable benchmarks made me want to make a silly, entertaining one instead.
So Claude and I built “Fun Bench”: a totally unscientific but delightful way to pit models against each other.
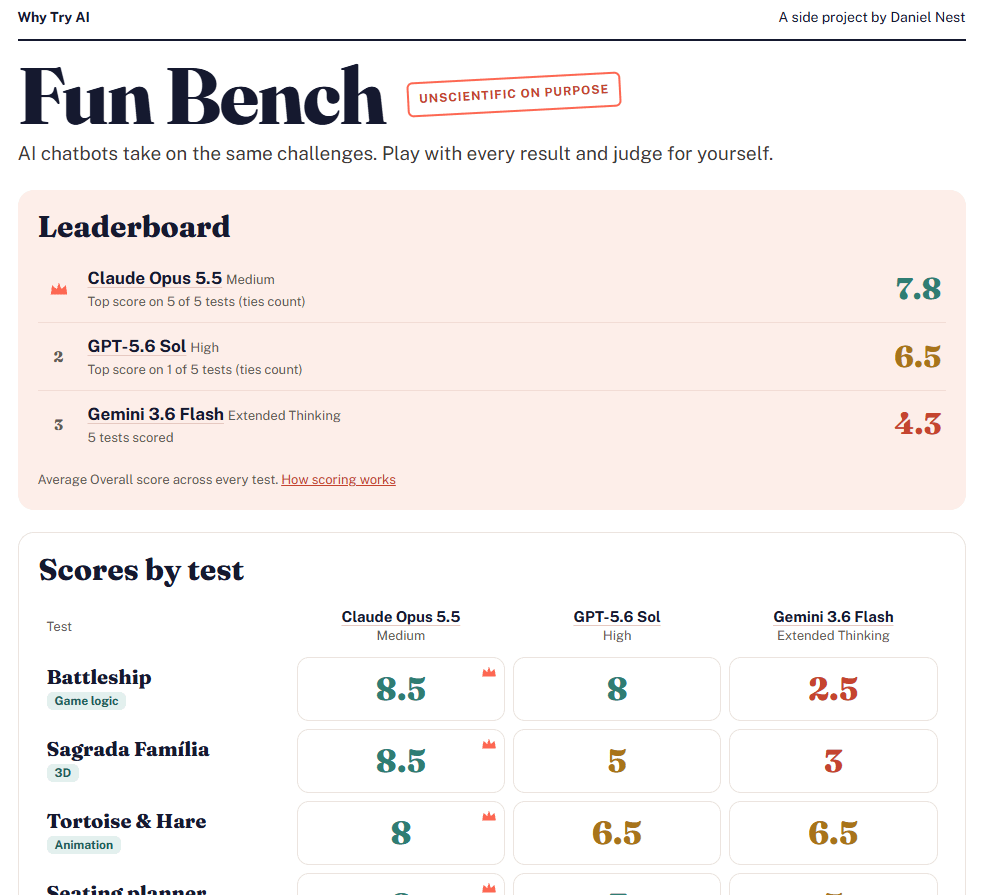
I kicked it off with three starter models and five starter tests, but I’ll be expanding the roster over time.
This was probably the most fun I’ve ever had working on a side project with AI.
I then asked my new best buddy Opus 5.5 to create a trailer for Fun Bench, so it did:
(Soundtrack and sound effects made by Opus using my free ElevenLabs account.)
Paid subscribers can see the score breakdowns, explore the actual results from every model, and submit suggestions (like models or tests to add) directly on the page.
Enjoy:

Thanks for reading!
If you enjoy my work, here’s how you can help:
❤️Like this post if it resonates with you.
🔄Share it to help others discover this newsletter.
🗣️Comment below. I love hearing from my readers.
🔓Support me and unlock cool perks by going paid:
Fun fact: My brain instantly mapped “Harvey’s Legal Agent Benchmark” to the chorus of the Teenage Mutant Ninja Turtles theme song. And now you see it too. You’re welcome.
Conveniently cherry-picked?
Default chat model in ChatGPT Plus at the time of writing
Default model for free Gemini accounts at the time of writing
Click the model links to see their full responses
The judge gave two separate scores (92 and 93 out of 100), but I’m letting it slide due to its “around” qualifier.